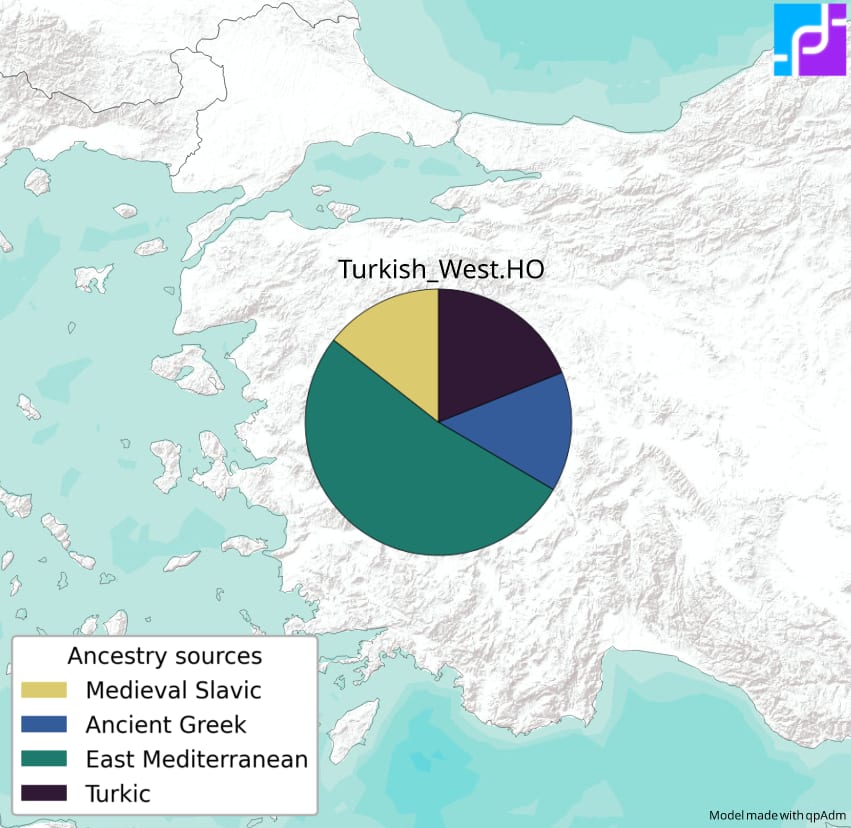
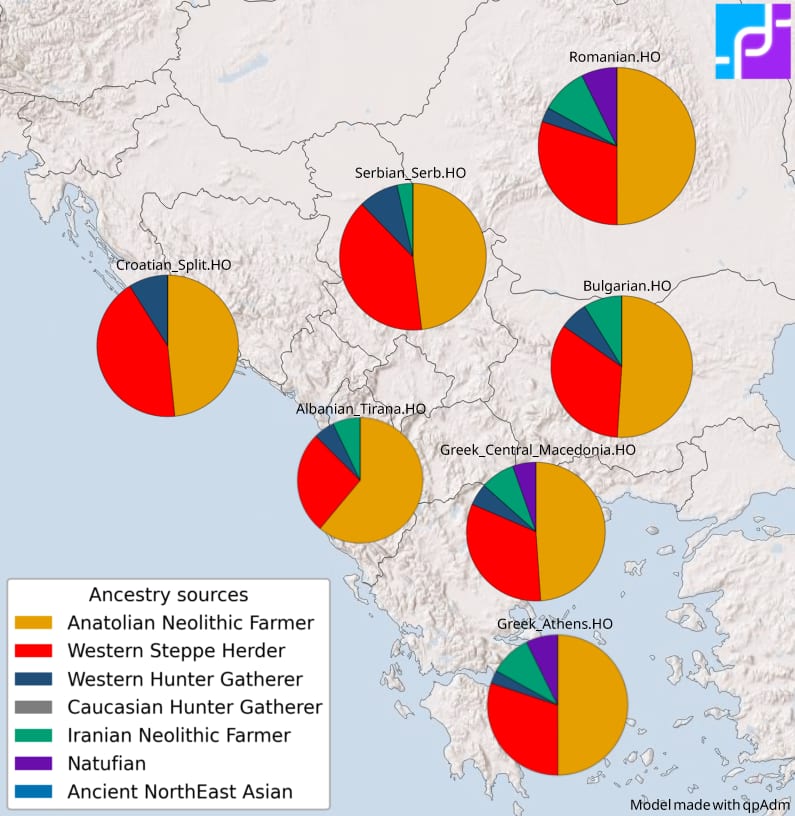
qpAdm is the formal admixture method of the ancient-DNA literature: it models one target population as a weighted mixture of chosen sources, measured against a set of outgroups, and unlike every percentage calculator it can reject a model outright. That property is why published papers lean on it, and why reading one takes more than reading percentages.
The articles here cover the method end to end: a structured learning path from the f4-statistics underneath to running models in R, the current best-practices checklist with where each rule comes from, the practical pipeline from a raw file to an AADR merge, the parameters that silently change results, population-specific model recipes for European, South Asian and Middle Eastern ancestry, the companion methods (qpGraph, f4-ratios, admixture dating), and worked examples from reports run against AADR v66.
What Ancient Ancestry, our paid qpAdm analysis, includes